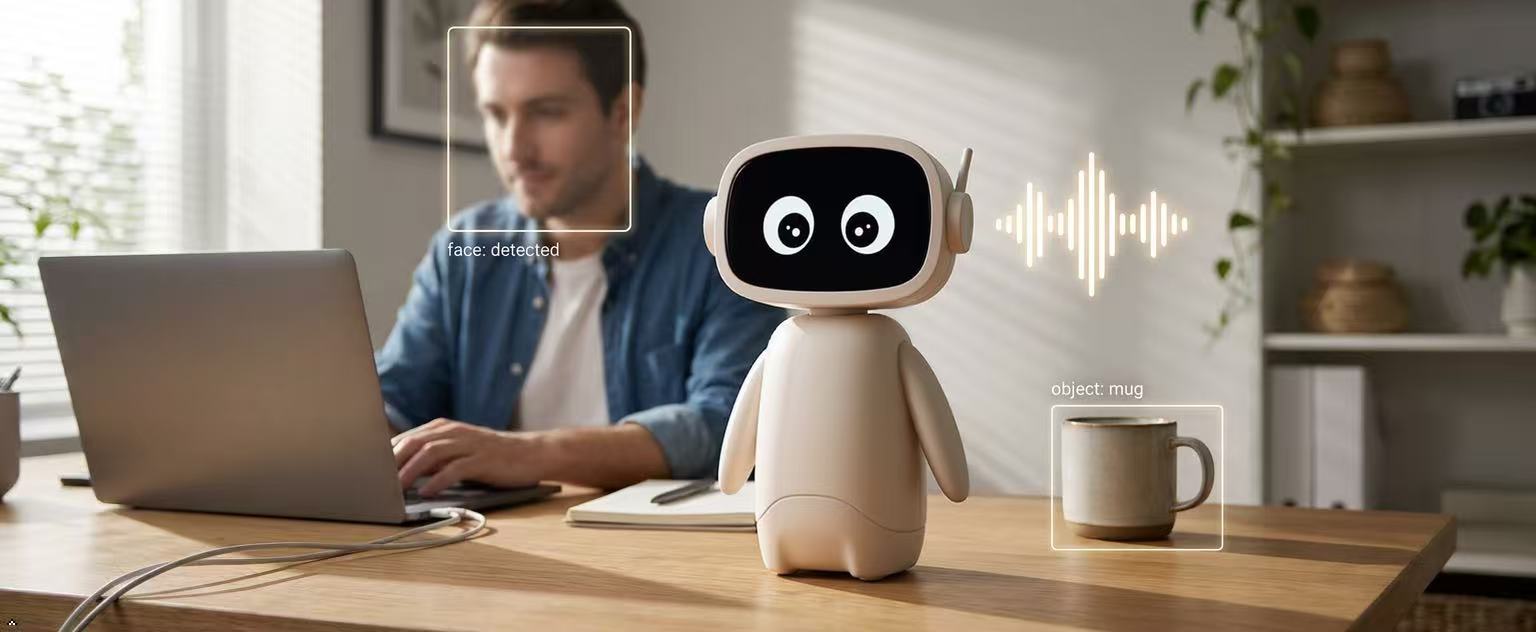
At TiMU, we built XiaoMu around a standard low-power edge SoC with a 1 TOPS NPU, a quad-core ARM processor, Debian, and 2–4GB RAM. Our goal was simple: create a voice interaction experience that never leaves the device. After months of integration and optimization, here is what 1 TOPS actually buys you, and where the edge breaks.
1. ASR is Feasible — But "Real-Time" Has a Texture
Whisper-base on the NPU runs at an RTF (Real-Time Factor) around 1.1–1.2 for 20-second audio chunks in FP16/INT8. In plain terms: it's roughly real-time for short utterances, but not for long-form streaming. You feel it as a slight lag after you stop speaking, not as a freeze. If you need continuous, low-latency transcription, 1 TOPS is the floor, not the comfortable zone.
2. The Real Bottleneck: 4GB RAM and the Thermal Wall
Our primary constraint isn't just compute; it's fitting the entire pipeline (OS + ASR + TTS + VAD) into a 4GB RAM footprint while keeping models accurate. We spent countless hours balancing model size and precision.
We tried faster-whisper to improve latency, but it was still too slow. Even worse, driving the CPU harder to meet real-time performance causes power consumption to spike. The chip then quickly hits thermal limits and throttles down, causing performance to drop further.
Here is a real top snapshot from the device running our final optimized pipeline. As you can see, we are pushing the 4GB limit to its absolute edge:
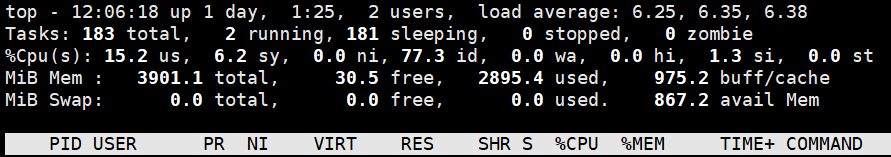
Before this optimization, the system would easily hit OOM (Out of Memory). We had to make heavy engineering compromises between latency, power efficiency, and thermal management just to make the experience stable and usable.
3. Why a Local LLM is Not the Play
We tried pushing a small LLM into the same box. You can technically get a 1.3B INT8 model running, but the performance metrics are unforgiving: 5–15 seconds per inference with a 256-token I/O cap, and memory peaks near 3GB.
That's not conversational latency. For a companion product, that delay destroys the illusion of a fluid conversation faster than any cloud call would. This is exactly why we designed XiaoMu with a hybrid architecture: the wake word, VAD, and ASR stay local for privacy and instant response, while the heavy LLM generation is optional and routed to the cloud.
4. Memory Bandwidth is the Quiet Killer
The NPU is fine for MobileNet/YOLO-class vision at 30fps and wake-word/command recognition. But every additional modality — camera, screen animation, audio I/O — competes for the same memory bus and the same small NPU cache. We learned to treat 1 TOPS as a budget for one primary model at a time. The moment you stack them, latency compounds.
The Takeaway for Edge Voice Builders
1 TOPS is a real, usable AI budget — but only if you design around its constraints. For XiaoMu, this means keeping the wake word and short-utterance ASR/TTS strictly on-device for instant response and absolute privacy, while letting the cloud handle heavy, open-ended generation.
If your product requires rich dialogue fully offline, you either step up to a 6+ TOPS SoC, or accept this hybrid path. We chose the hybrid path, and it's the only one that kept latency inside the range where a human will keep talking to the device.
TiMU Technology builds XiaoMu, a privacy-first AI companion robot. If you are interested in on-device AI, ROS2 applications, desktop robot development, or OEM/ODM partnerships, feel free to reach out to us.